The Laboratory Average Looked Perfect, but One Outlier Changed the Entire Result: Why Research Data Need More Than a Summary Number
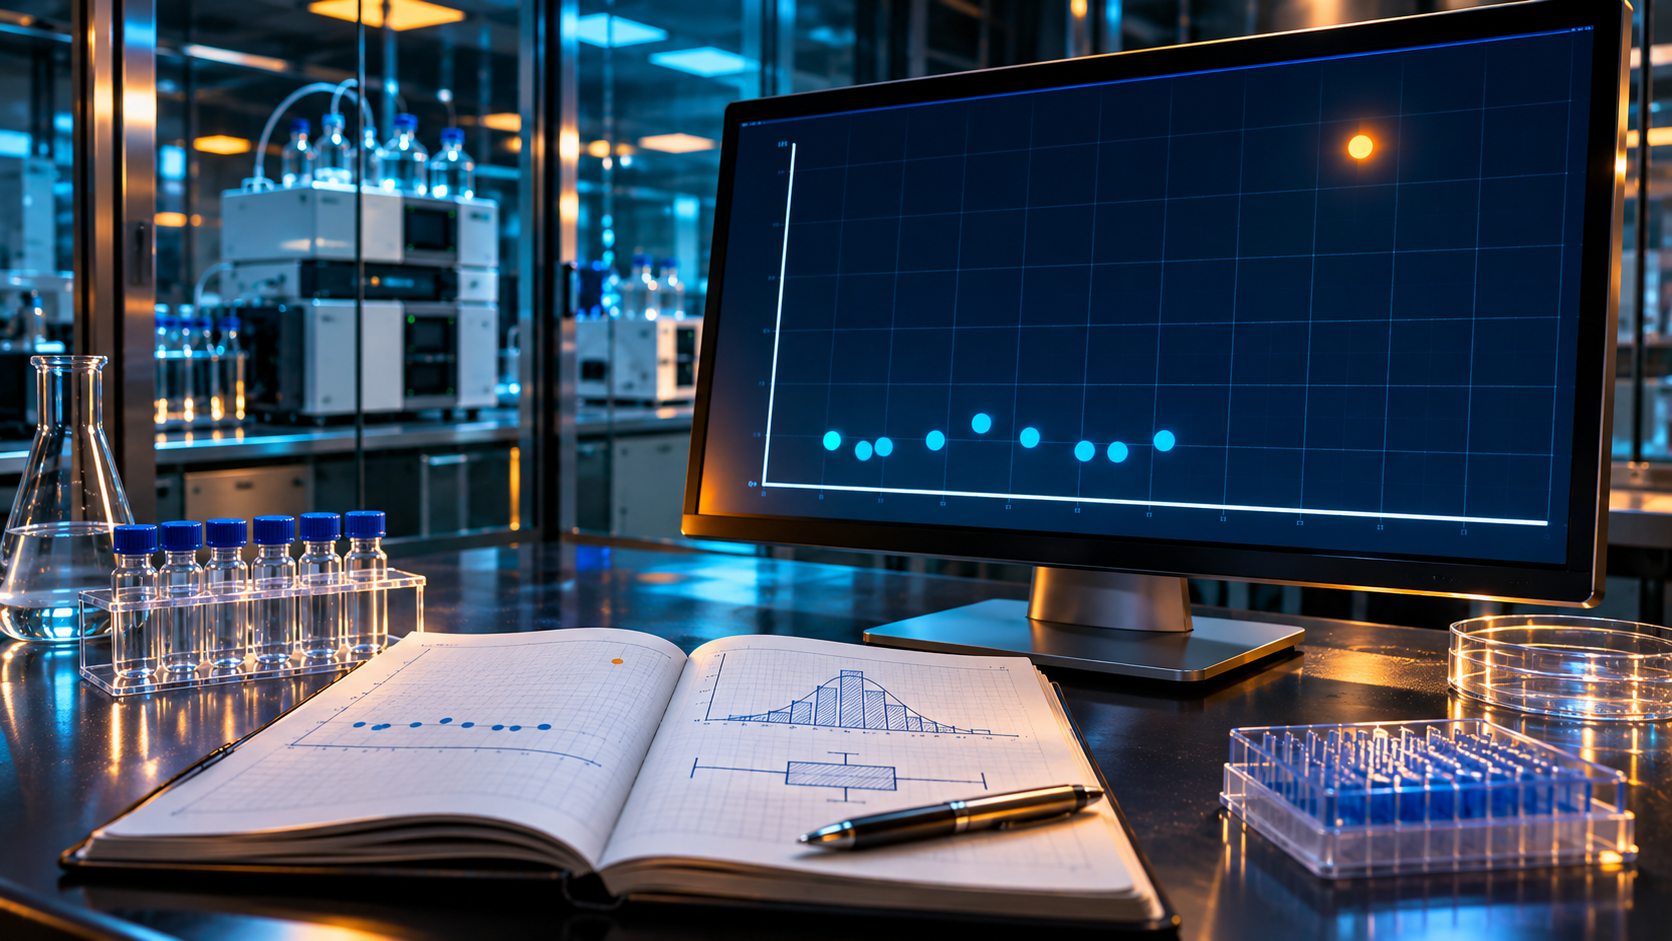
Imagine a laboratory examining ten measurements from a research experiment. Nine observations fall within a relatively narrow range, while the tenth is much higher. The researcher calculates an average, adds the result to a report and prepares a graph showing what appears to be a satisfactory overall outcome.
Then another scientist examines the individual measurements.
The unusual observation changes the average enough to affect the interpretation. Suddenly, the summary number no longer seems to describe what happened in most of the experiment. The team must determine whether the result reflects a measurement error, a problem with the sample, an unexpected experimental condition or a genuine phenomenon worth investigating.
This hypothetical situation highlights a central challenge in scientific research. Summary statistics help investigators communicate large amounts of information, but they can also conceal important variation. A carefully calculated average is not necessarily a complete account of the underlying evidence.
In laboratory research involving peptides and other chemical materials, the distinction matters because measurement results can be influenced by sample characteristics, analytical techniques and experimental conditions. A trustworthy conclusion requires more than one attractive number.
Why the Average Does Not Tell the Whole Story
The arithmetic mean is calculated by adding observations and dividing by the number of observations. It is useful in many scientific settings because it summarizes the central tendency of a dataset.
However, the mean is sensitive to unusually high or low values.
Consider five hypothetical laboratory measurements: 10, 11, 10, 12 and 47. Their arithmetic mean is 18, even though four of the five observations fall between 10 and 12.
The median, or middle observation after sorting the values, is 11. The difference between the mean and median tells readers something important about the distribution.
Neither result is automatically the correct summary. The appropriate statistic depends on the scientific question, the measurement process and the assumptions underlying the analysis.
For example, an extreme value might be a legitimate part of the population being studied. In other circumstances, it could result from an identifiable analytical mistake. Treating those situations as equivalent would be scientifically inappropriate.
Researchers should therefore examine the data distribution rather than assuming that one measure of central tendency captures every important feature.
What Scientists Mean by an Outlier
An outlier is an observation that appears unusually distant from other values in a dataset. Its presence may be important, but its meaning is not immediately obvious.
The National Institute of Standards and Technology explains that potential outliers can arise from data errors, incorrect experimental procedures, random variation or scientifically interesting phenomena.
This distinction prevents a common mistake: assuming that an unusual value must be invalid simply because it differs from the rest.
In a laboratory experiment, an extreme observation could result from incorrect transcription, instrument problems, changes in sample preparation or unexpected chemical behavior.
Each possibility leads to a different response. A confirmed transcription error may be corrected using the original record. An instrument malfunction may justify excluding a measurement under a documented procedure. A valid but unusual observation may need to remain in the analysis.
The proper objective is to understand the value, not to force the dataset into a more visually appealing pattern.
Why Deleting the Unusual Result Can Create a Bigger Problem
Removing an inconvenient measurement can make a scientific result look cleaner. It may reduce apparent variation, change the average and increase the statistical significance of a comparison.
Those changes are not necessarily evidence that the revised analysis is more accurate.
NIST’s statistical handbook distinguishes identifying potential outliers from determining how they should be handled. It specifically warns against simply discarding unusual observations when researchers cannot establish that they are erroneous.
Imagine a study in which one sample produces a result that contradicts the expected trend. If investigators remove the observation without an appropriate scientific justification, the remaining dataset may present a misleading picture of experimental consistency.
Conversely, retaining a value known to come from an instrument failure could also distort the analysis.
The solution is not a universal rule to include or exclude every outlier. It is a transparent process that explains why particular observations were treated differently.
Whenever exclusions materially affect the conclusions, presenting analyses with and without the affected values can help readers understand the result’s sensitivity.
How the Median and Robust Statistics Add Context
Robust statistical methods are designed to reduce the influence that extreme observations can exert on certain estimates.
The median is a familiar example. Because it describes the middle of an ordered dataset, a single unusually high value generally has less influence on it than on the arithmetic mean.
In a 2000 paper published by the National Institute of Standards and Technology, J. W. Müller examined possible advantages of using robust methods for evaluating measurement comparisons. The work explained why median-based approaches can offer useful alternatives to ordinary averages when outlying observations affect a result.
That does not mean the median should always replace the mean. Some scientific questions concern total quantities or expected values for which the arithmetic mean is appropriate.
Other questions may be better addressed by robust estimates, particularly when the data distribution contains extreme observations.
Researchers can gain a fuller understanding by examining more than one statistical summary, especially when a small number of measurements strongly influence the final conclusion.
Why Laboratory Measurements Need an Uncertainty Statement
Every experimental measurement involves uncertainty. Instruments have limitations, sample preparation can vary, and environmental or analytical conditions may influence results.
Reporting a value without explaining its uncertainty can make a measurement appear more definitive than the available evidence supports.
NIST’s guidelines for evaluating and expressing measurement uncertainty emphasize documenting uncertainty components, analytical procedures and the assumptions used in reporting results.
Consider two laboratories measuring the same scientific quantity. They may obtain slightly different numerical values without their findings being genuinely contradictory.
To evaluate the disagreement, researchers need to consider the uncertainty associated with each measurement and whether the methods address the same quantity.
An average without a measure of variability or uncertainty provides only part of that information.
The most informative reporting includes a clearly defined measurement, suitable statistical summaries and enough methodological context for readers to understand what the numbers mean.
The Difference Between Variation and Measurement Error
Not every difference between observations is a mistake.
Scientific experiments can contain natural variability, particularly when measurements involve biological systems. Even carefully controlled laboratory processes may produce different outcomes across repeated observations.
Measurement error is a distinct concept. It concerns differences between a measured result and the quantity being estimated, although the exact error may not be known.
Researchers need to consider whether observed variation reflects the properties of the system, the measuring procedure or both.
For example, repeated measurements of a stable chemical reference material may help evaluate the performance of an analytical method. Repeated biological experiments may reveal variation associated with the model being investigated.
Those two forms of variability should not automatically be combined or interpreted in the same way.
Understanding their sources makes the reported average more meaningful and helps determine whether a surprising observation deserves additional investigation.
Why Sample Identity Matters Before Statistical Analysis Begins
A statistical method cannot compensate for uncertainty about what a laboratory actually tested.
In peptide research, a sample’s label is not independent confirmation of its molecular identity, purity or composition. Appropriate analytical characterization and documentation help establish which material was involved in an experiment.
Imagine two research groups reporting measurements under the same compound name. If the samples differ in relevant chemical properties, the resulting numerical variation may reflect material differences rather than disagreement about the underlying biological process.
This is one reason readers examining this research information resource should distinguish general educational explanations from material-specific scientific evidence.
A strong laboratory report connects analytical conclusions to clearly identified samples, suitable measurement procedures and records that allow investigators to understand the context of each result.
Without that foundation, even sophisticated statistical analysis may provide false confidence.
When Independent Testing Finds Different Results
Independent testing can help researchers evaluate whether a measurement is consistent across analytical settings. However, disagreement between laboratories requires investigation rather than an automatic assumption that one laboratory is wrong.
Different analytical instruments may have different performance characteristics. Methods may measure related but nonidentical properties, and sample preparation can introduce variation.
NIST provides guidance on consensus means for measurements collected by different laboratories or methods. Its documentation explains that simple averages can become distorted when results contain outliers or when laboratories differ in their measurement variability.
That context is relevant to discussions of independent laboratory testing, but a general description of testing cannot establish the results of any particular sample.
Investigators should examine which method was used, what quantity was measured and how uncertainty was evaluated before deciding whether two reports genuinely conflict.
A difference between measurements may reveal a problem, but it may also identify conditions under which the original conclusion needs refinement.
Why a Lot Number Can Be Important to Data Interpretation
Laboratory results need to be associated with the correct research materials.
A lot number may help distinguish one production or preparation group from another. It can support recordkeeping and traceability when the identifier is consistently linked to appropriate documentation.
That connection becomes important when researchers compare results obtained at different times or in different laboratories.
If observations from multiple lots are combined without considering material differences, the final average may conceal variation that is scientifically relevant.
For instance, a study may examine whether a measured property remains consistent across separate material groups. Combining all measurements into one number could make it difficult to identify differences between groups.
Readers can explore the general subject of lot identification through resources such as https://www.usapeptidedepot.com/research/why-lot-numbers-matter, while remembering that traceability claims must be evaluated against the actual records maintained for the material.
The existence of a lot number alone does not establish scientific quality. Its value depends on the evidence connected to it.
How Graph Design Can Conceal the Outlier
A visual summary can make complicated measurements accessible, but it can also hide the variation that matters most.
Consider a bar chart showing only the average for two experimental groups. If one group contains an extreme result, the difference between the bars may be driven largely by that single observation.
Readers who cannot see the individual measurements may assume the groups are consistently different.
A dot plot or other suitable display of individual observations can reveal the underlying distribution more clearly when the number of observations permits it.
Box plots may also provide useful information about central tendency and spread, although their interpretation depends on sample size and statistical conventions.
Researchers should choose visualizations that communicate the relevant properties of the data rather than simply producing the most dramatic contrast.
Reporting the number of independent observations is equally important. Multiple measurements from one preparation do not necessarily provide the same evidence as measurements from independent experiments.
Why Small Sample Sizes Deserve Additional Caution
A small dataset can be particularly sensitive to unusual observations.
When only a few measurements are available, a single extreme value may change both the estimated average and the calculated variability.
Small samples also make it difficult to determine the shape of an underlying distribution with confidence.
This does not make small studies worthless. Exploratory experiments often generate useful questions and help researchers refine methods for future investigation.
However, strong general claims require evidence appropriate to their scope.
A preliminary finding should be described as preliminary when its uncertainty remains substantial. If a result appears sensitive to the inclusion of one observation, that sensitivity deserves attention.
Researchers may use additional measurements, independent experimental runs or appropriately selected statistical procedures to investigate the finding.
The objective is to determine whether the observed pattern reflects a reliable property of the system rather than a fragile summary of a small dataset.
The Hidden Danger of Combining Incompatible Measurements
Combining data can increase the amount of information available for analysis. It can also create misleading results when observations were collected under materially different conditions.
For example, measurements from different instruments, analytical methods or sample groups may not be directly comparable without suitable evaluation.
Differences in calibration, measurement range or experimental preparation can influence the distribution of the combined dataset.
An overall average may conceal patterns within individual groups. Conversely, separate group averages may reveal systematic differences that were hidden when the data were pooled.
Researchers should consider whether observations can reasonably be treated as measurements of the same underlying quantity under comparable conditions.
NIST’s laboratory guidance emphasizes understanding the measurement system and investigating changes that may influence its statistical behavior.
The decision to combine measurements therefore requires scientific justification, not merely the convenience of producing a single summary number.
How Researchers Can Investigate an Unexpected Observation
When a measurement appears unusual, the first step is to examine the original evidence.
Investigators may review transcription records, instrument output, sample identifiers and relevant analytical conditions to determine whether an identifiable problem occurred.
They can compare the observation with technical controls or other measurements generated under suitable conditions.
If the value appears scientifically valid, researchers may investigate whether its presence reveals a limitation of the initial model or an important characteristic of the experimental system.
Statistical analysis can then help assess how sensitive the findings are to different reasonable assumptions.
NIST recommends distinguishing the identification of an outlier from the choice of how to accommodate it. Robust statistical methods may help when unusual observations cannot justifiably be removed.
Any changes to the original analysis should be documented, particularly when they alter the interpretation.
This approach makes an unexpected value a subject for scientific investigation instead of an inconvenience to be erased.
Why Transparent Reporting Strengthens Scientific Credibility
A reliable research report explains how the data were collected, how unusual observations were handled and why particular analytical methods were selected.
Readers should be able to identify the number of observations, their relevant grouping and the statistical summaries used to describe them.
When applicable, reporting both conventional and robust analyses can show whether the central conclusion depends heavily on extreme values.
Researchers should also describe important limitations, including measurement uncertainty, missing observations and constraints on generalizing the findings.
Transparency does not guarantee that an experiment is correct. It makes the evidence easier to evaluate and gives independent investigators a clearer basis for examining the conclusions.
This is particularly important in emerging scientific fields where preliminary laboratory findings may attract attention before their reliability has been established across multiple settings.
A responsible interpretation separates what the observations demonstrate from what remains uncertain.
What the Outlier Teaches Us About Better Science
A dataset can produce a mathematically correct average and still leave important scientific questions unanswered.
An outlier may indicate a mistake, but it may also reveal a real feature of the system under investigation. Deciding between those possibilities requires examination of the experiment and the measurement process.
NIST’s work on outlier detection, robust statistical methods and measurement uncertainty shows why investigators should look beyond one summary number.
For peptide-related laboratory research, meaningful interpretation also depends on sample identity, analytical comparability, transparent records and the distinction between experimental findings and broader health claims.
The most trustworthy scientific report is not necessarily the one with the smoothest graph or the most convenient average. It is the one that explains what was measured, acknowledges uncertainty and allows readers to see how the conclusion follows from the evidence.
Sometimes the observation that does not fit the pattern is the one that reveals what researchers still need to understand.